Lecture image placeholder

Premium content

Access to this content requires a subscription. You must be a premium user to view this content.

Monthly subscription - $9.99Pay per view - $4.99Access through your institutionLogin with Underline account
Need help?
Contact us
Lecture placeholder background

COLING 2022

•

October 12, 2022

•

Gyeongju , Korea, Republic of

Please log in to leave a comment

Downloads

PaperTranscript English (automatic)
access premium content

Next from COLING 2022

How to Adapt Pre-trained Vision-and-Language Models to a Text-only Input?
poster

How to Adapt Pre-trained Vision-and-Language Models to a Text-only Input?

COLING 2022

Lovisa Hagström
Lovisa Hagström and 1 other author

12 October 2022

Similar lecture

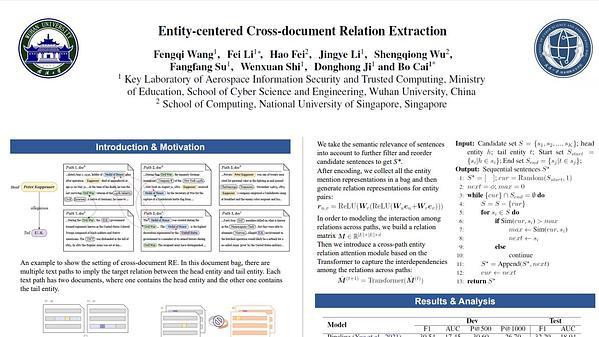
Entity-centered Cross-document Relation Extraction
poster

Entity-centered Cross-document Relation Extraction

EMNLP 2022

Fengqi Wang
Fengqi Wang

10 December 2022