EMNLP 2023

•

December 08, 2023

•

Singapore

Please log in to leave a comment

Downloads

SlidesPaperTranscript English (automatic)

Next from EMNLP 2023

Can Pre-trained Vision and Language Models Answer Visual Information-Seeking Questions? | VIDEO
poster

Can Pre-trained Vision and Language Models Answer Visual Information-Seeking Questions? | VIDEO

EMNLP 2023

Yang Chen
Ming-Wei Chang
+4
Yang Chen and 6 other authors

08 December 2023

Similar lecture

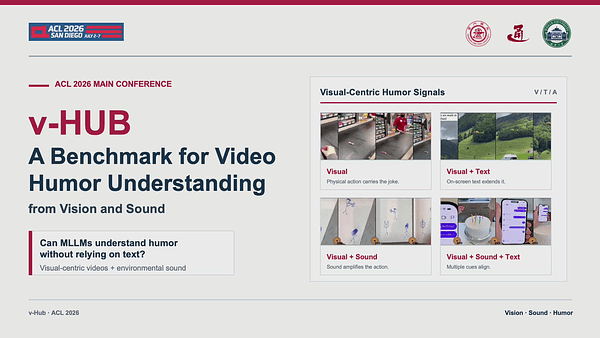
v-HUB: A Benchmark for Video Humor Understanding from Vision and Sound
technical paper

v-HUB: A Benchmark for Video Humor Understanding from Vision and Sound

ACL 2026

+6
Wei Bi and 8 other authors

07 July 2026